
ASRock Intel Arc Pro B60 Creator 24GB Graphics Card
3.9Editor score
24GB GDDR6 memory
Intel Xe2-HPG architecture
PCIe 5.0 support
Find the best GPU for Llm in 2026. We compare top models for performance, VRAM, and AI inference to help you choose the right hardware.
Choosing the right GPU for Llm development requires balancing raw power with memory capacity. Modern workloads demand high bandwidth and efficient inference capabilities to run models smoothly.
We evaluated ten top-tier graphics cards based on architecture, VRAM size, and specialized AI accelerators. Each entry offers distinct advantages for different budget ranges and use cases.
This guide details key specifications and practical applications for every pick. Prices and availability fluctuate frequently, so verify current details before making your final hardware decision.
3.9Editor score

4.6Editor score

4.3Editor score
This table provides a side-by-side view of key specifications across all ten products. Compare memory, architecture, and cooling features to find the ideal match for your specific AI tasks.


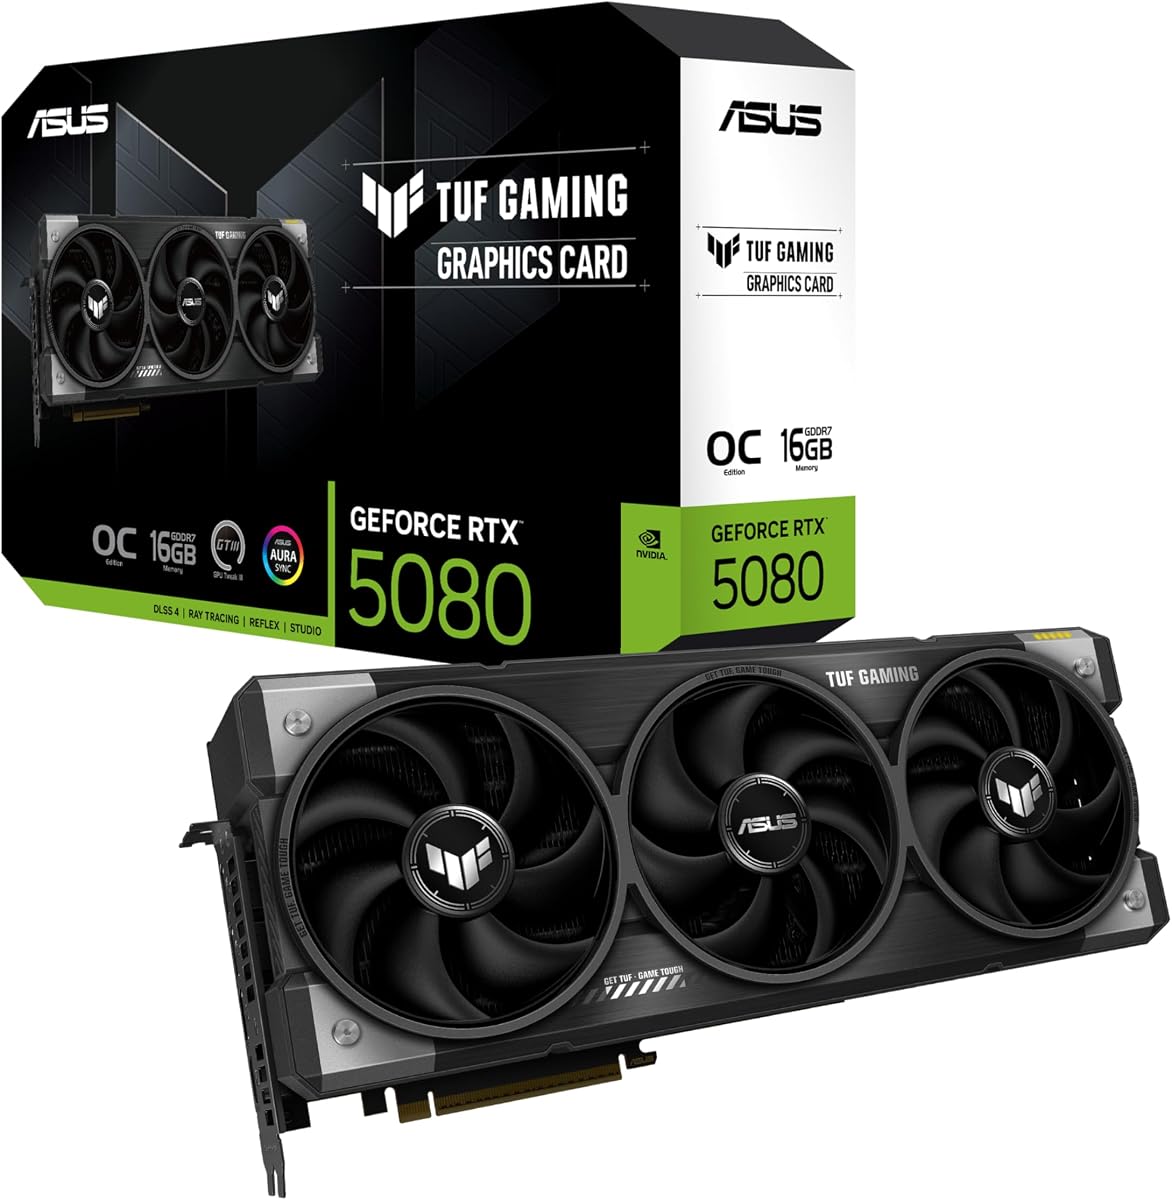


This card ranks highest for overall value in our selection. It combines powerful architecture with dedicated cooling to handle demanding workloads efficiently.
We may earn a commission when you buy through this link, at no additional cost to you.
The NVIDIA Blackwell architecture supports advanced inference and training tasks. High bandwidth ensures data moves quickly between memory and compute units.
Cooling remains quiet even under sustained loads. However, you will need a strong PSU to handle peak power demands during intensive sessions.
Enthusiasts and professionals seeking balance will find this ideal. It handles most local models well without needing enterprise-level costs.
GDDR7 memory provides the bandwidth needed for rapid token generation during inference tasks.
The WINDFORCE system maintains safe temperatures during long training or rendering sessions.
We may earn a commission when you buy through this link, at no additional cost to you.
This model stands out for its massive 24GB memory at a lower cost. It is designed specifically for workstation and AI inference tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
Intel's Xe2-HPG architecture offers solid acceleration for specific AI frameworks. The large VRAM allows loading bigger models without external storage.
Driver maturity can lag behind NVIDIA. Users must verify software compatibility before purchase to ensure smooth integration with existing tools.
Developers with tight budgets should consider this option. It provides significant memory headroom for experimentation and smaller production deployments.
The 24GB capacity enables running larger local models without aggressive quantization techniques.
Optimized for multi-GPU setups, allowing performance scaling across multiple cards over time.
We may earn a commission when you buy through this link, at no additional cost to you.
This workstation card delivers unmatched memory capacity for heavy workloads. It is engineered for teams requiring high stability and security.
We may earn a commission when you buy through this link, at no additional cost to you.
The 96GB DDR7 ECC memory eliminates bottlenecks for massive datasets. Tensor cores accelerate fine-tuning and inference significantly.
The cost is substantial and requires strict export compliance. It is best suited for research labs rather than individual consumers.
Enterprises needing maximum performance without compromise should choose this. It scales well in multi-GPU environments for intensive tasks.
ECC memory ensures data integrity during long computations for critical applications.
Universal MIG allows splitting the GPU for secure concurrent workflows across different users.
We may earn a commission when you buy through this link, at no additional cost to you.
This card offers a compelling alternative for AMD users. It features 32GB memory and specialized AI accelerators for efficient processing.
We may earn a commission when you buy through this link, at no additional cost to you.
The RDNA 4 architecture balances rendering and compute tasks well. Vapor chamber cooling ensures stability during long continuous operations.
Driver optimization is critical for AI performance. Users may need to fine-tune settings for maximum efficiency in specific applications.
Professionals requiring high VRAM without enterprise pricing should consider this. It fits well into server racks and workstations.
The vapor chamber ensures consistent performance even under heavy sustained loads.
Dedicated accelerators handle complex tasks more efficiently than standard compute units.
We may earn a commission when you buy through this link, at no additional cost to you.
This model balances gaming and AI at a reasonable price. It features 16GB memory and robust cooling for mixed workloads.
We may earn a commission when you buy through this link, at no additional cost to you.
High clock speeds help maintain responsiveness during interactive inference. The cooling system keeps noise low even when stressed.
It lacks specialized software compared to workstation cards. Users must rely on general frameworks for AI acceleration tasks.
Casual developers needing extra VRAM will find this useful. It handles smaller models well and saves budget for other components.
Dual fans provide sufficient airflow to maintain optimal operating temperatures.
Designed for high performance graphics, it also handles general compute tasks efficiently.
We may earn a commission when you buy through this link, at no additional cost to you.
Built for longevity, this card offers robust protection against dust and moisture. It performs AI tasks efficiently with high bandwidth memory.
We may earn a commission when you buy through this link, at no additional cost to you.
Phase-change thermal pads improve heat transfer over time. The TUF design ensures stability even in demanding environments.
It requires significant case clearance. The specific power connector might need adapters for older systems.
Builders prioritizing reliability will appreciate this choice. It fits well in long-term setups requiring consistent performance.
Coated PCBs prevent corrosion and short circuits in varied conditions.
Phase-change materials ensure sustained cooling performance over years of use.
We may earn a commission when you buy through this link, at no additional cost to you.
This compact card fits well in dense server racks. It includes 32GB memory and dedicated accelerators for local inference.
We may earn a commission when you buy through this link, at no additional cost to you.
The turbo cooler moves air directly out of the chassis. Bearings are rated for longer life to reduce maintenance.
Single fan designs can be louder at max speeds. Ensure your case has proper ventilation to avoid thermal throttling.
System integrators needing density will value this option. It packs power into a standard two-slot footprint effectively.
Designed for tight spaces without sacrificing memory capacity or cooling.
Ball bearings provide durability and consistent cooling over extended operation.
We may earn a commission when you buy through this link, at no additional cost to you.
This card offers a compact entry point for local AI. It provides 16GB memory in a small, efficient package.
We may earn a commission when you buy through this link, at no additional cost to you.
Axial-tech fans maximize airflow despite the small size. Silent mode ensures low noise during lighter tasks.
It is not suitable for heavy training loads. However, it handles inference and fine-tuning for smaller models well.
Users with limited desk space will find this ideal. It balances size and capability for personal projects.
Fans stop completely at low loads for a completely silent experience.
Compact dimensions allow installation in smaller cases without compromise.
We may earn a commission when you buy through this link, at no additional cost to you.
This accelerator targets high-performance computing environments. It offers 48GB memory for large batch processing and training.
We may earn a commission when you buy through this link, at no additional cost to you.
The design prioritizes throughput over consumer features. It is optimized for server racks and cooling environments.
Setup requires enterprise knowledge and infrastructure. The cost is high for individual users but justified for teams.
Organizations needing robust AI pipelines should consider this. It ensures stable performance under constant heavy loads.
Built for servers with robust cooling and long-term stability.
Optimized for processing large datasets quickly and reliably.
We may earn a commission when you buy through this link, at no additional cost to you.
This unit offers massive memory in an efficient max-Q form. It is ideal for massive models that do not fit elsewhere.
We may earn a commission when you buy through this link, at no additional cost to you.
The bus width ensures high bandwidth for data transfer. Power limits protect the system while maintaining high performance.
Retail packaging is not included. This adds complexity for individual builders but suits integrators better.
Researchers needing maximum memory locally will find this essential. It bridges the gap between workstations and supercomputing.
Engineered for peak performance within lower thermal constraints.
512-bit bus delivers massive bandwidth for complex model data.
We may earn a commission when you buy through this link, at no additional cost to you.
Selecting the right GPU requires balancing memory, architecture, and budget. This section explains the key factors that impact performance.
VRAM size determines how large a model you can load. Larger models require 24GB or more for smooth local inference.
Always prioritize memory capacity to avoid bottlenecks during complex AI workloads.
Bandwidth affects how quickly data moves between memory and cores. Faster memory enables quicker token generation.
High bandwidth is essential for responsive inference and rapid model training.
Modern architectures include specialized AI cores for efficient processing. Check for Tensor or AI accelerators for best results.
Choose newer generations for better support and efficiency in AI frameworks.
Sustained workloads generate significant heat. Efficient cooling ensures stability and longevity during long runs.
Look for robust systems with quality materials for consistent performance.
High-performance cards demand significant wattage. Verify your PSU meets the specific connectors and total power needs.
Adequate power ensures stability and prevents system crashes during peak loads.
Compatibility with frameworks like PyTorch and TensorFlow is vital. Ensure driver support is mature for your tools.
Strong software support simplifies setup and reduces troubleshooting time.
Some models allow adding multiple cards for increased capacity. Check if the system supports scaling effectively.
Scalable designs offer future-proofing as your needs grow.
Durable construction prevents failure under constant use. Look for military-grade components and protective features.
Robust hardware ensures long-term reliability for daily AI tasks.
Install the latest drivers and update your AI frameworks before starting any workload. This ensures maximum compatibility and performance.
Maintain proper airflow in your system by cleaning dust from fans regularly. Dust buildup reduces cooling efficiency and risks overheating.
Monitor temperatures during long inference sessions to ensure stability. Use system tools to track usage and avoid thermal throttling.
At least 16GB is recommended for basic tasks. Larger models often require 24GB or more to run without issues. More memory allows running bigger models locally.
NVIDIA is generally preferred due to broader framework support. However, AMD is improving with dedicated AI accelerators. Check specific tool compatibility first.
Yes, many models support multi-GPU scaling to increase memory. Ensure your software and drivers support distributed inference. Linux often offers better support for this.
If you also game, gaming GPUs offer better compatibility. Workstation cards are optimized for compute. Choose based on your primary workflow needs.
Yes, newer generations include better AI cores and efficiency. They handle modern tasks faster with lower power usage. Investing in newer tech usually pays off.
New cards offer warranty and reliability crucial for professional work. Used cards carry risks of hidden wear. Prioritize warranty support for critical AI tasks.
Our top picks cover a wide range of needs from budget to premium. The GIGABYTE RTX 5080 offers excellent balance for most users.
Focus on memory capacity and compatibility with your specific tools. These factors matter more than raw power alone for most inference tasks.
Always check current prices and availability before purchasing. Hardware markets change quickly, so stay flexible with your final selection.